IAM & access control
Reviewed users, roles and policies, tightened account and password controls, reduced excessive and privileged permissions, and applied least privilege across service roles.
Cost, reliability, Kubernetes and compliance engagements for teams running real workloads on AWS. Each one covers the problem, how we worked, and what changed.
Client names are withheld at their request. Industry, region and results are shared with permission.
How Cloudico cut a digital media platform’s monthly AWS spend by 55% while fixing an AWS WAF issue that was blocking search-engine crawling.
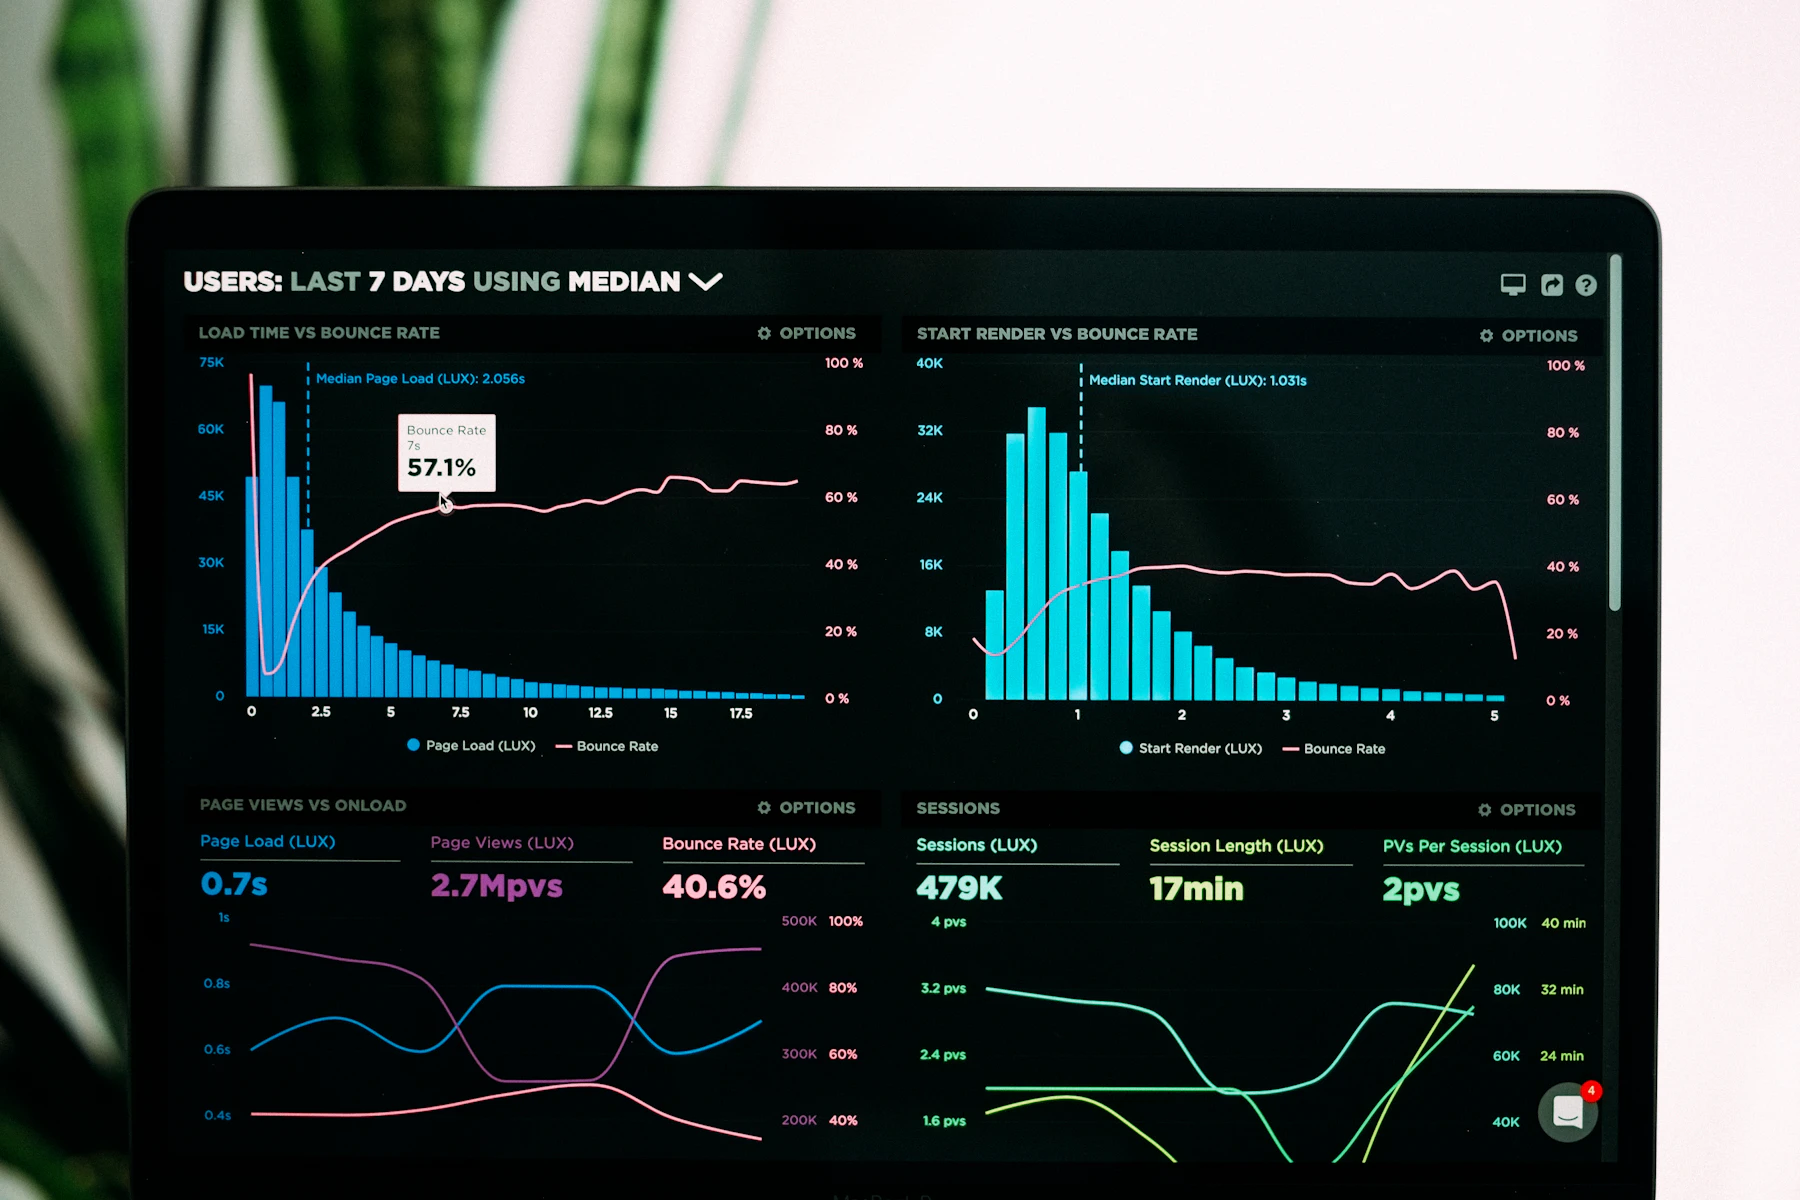
A digital media platform came to Cloudico after two serious problems surfaced at the same time.
AWS spend had grown more than 30x in four months with no matching increase in application traffic. The monthly bill was over budget and still climbing.
In the same period, Google crawl activity fell by about 97% within five days, and newly published articles stopped appearing in search results. For a publisher that depends on organic search, both problems hit revenue directly.
The crawl drop lined up with recent AWS WAF rule changes, so the client needed two answers without risking performance, capacity or security: was AWS causing the crawl failure, and where was the extra spend really coming from?
We treated the engagement as a measurement exercise, not a configuration review. Configuration shows how infrastructure is meant to behave; metrics and logs show what actually happened. An aggressive rightsizing or a wrong WAF change could have caused a bigger production problem.
Share of total identified savings. Every recommendation was tied to measured utilization.
Buying reserved capacity before rightsizing would have locked the client into an oversized footprint for the full term.
We also found two production containers already running at their configured resource ceilings. Cutting them based on average utilization would have caused instability, so they were left untouched.
The root cause was an AWS WAF rate-limiting rule applied broadly to all incoming traffic. Legitimate search crawlers send large request volumes from a narrow set of addresses, which makes them easy to catch in a badly placed rate limit. The rule order also meant crawler verification could not run before the rate limit was applied.
After correcting the rule order, we checked the result in traffic and WAF logs. We did not trust the User-Agent header, which is easy to spoof. Traffic was verified against the search engine’s published crawler network ranges.
What the logs showed
of verified crawler traffic reached the site after remediation
of verified crawler traffic was blocked
of blocked “crawler” requests were impersonators, so the WAF control stayed in place
We analyzed utilization and spend across application compute, ECS workloads, databases, cache infrastructure, reserved capacity, AWS support, logging and delivery services. Each recommendation came with the conditions required to implement it safely.
The goal was not simply a smaller bill. It was to establish what could be optimized safely and what needed to stay as it was.
Once AWS was confirmed to be letting legitimate crawlers through, the remaining indexing investigation moved to the application layer. That stopped the team from repeatedly changing WAF or CloudFront settings that were already working.
The environment had almost no meaningful reserved-capacity coverage. That became an additional savings opportunity once the correct infrastructure baseline was in place.
Recommendations were delivered as a staged rollout with verification points between major changes, rather than as a single high-risk cost-cutting exercise.
AWS bill growing faster than your traffic? We’ll show you where the spend goes and what is safe to cut.
How Cloudico helped an electronic trading platform reach 99.95% availability, ship deployments 80% faster and cut manual infrastructure changes by 90%.

The client runs an electronic trading platform where availability, security and performance are critical to daily business. As transaction volumes and usage grew, the infrastructure started holding the engineering team back.
The goal was to modernize the AWS environment without disrupting active trading, and to make infrastructure changes automated, repeatable, secure and observable.
Multi-AZ deployment, Elastic Load Balancing, Auto Scaling, RDS Multi-AZ, central monitoring and automated infrastructure management, introduced together.
Because the platform supports live financial operations, modernization was introduced step by step, with rollback available at every critical stage.
Result: the production infrastructure was modernized with zero critical downtime for active trading.
Workloads run across multiple Availability Zones. Elastic Load Balancing sends traffic only to healthy instances, and EC2 Auto Scaling adjusts capacity to demand, so engineers no longer add servers by hand during busy trading periods. Amazon RDS Multi-AZ provides database redundancy and failover, and Route 53 completes the resilient setup.
Infrastructure configuration was standardized so environments can be provisioned consistently and repeatedly. Deployment workflows were redesigned to remove repetitive steps, which made releases faster and more predictable and reduced configuration errors across environments.
Amazon CloudWatch provides central monitoring, logging and alerting for availability, EC2 health and utilization, load balancer and database health, scaling activity, errors and operational events. The team now sees problems earlier, before they grow into service disruptions.
AWS IAM limits access to what is needed. AWS KMS handles encryption and AWS Secrets Manager stores application credentials. Amazon VPC and Security Groups control network access, AWS WAF protects internet-facing traffic, and AWS CloudTrail records API activity and infrastructure changes.
Business continuity was designed into the architecture. AWS Backup, Amazon RDS backups, Amazon S3 and documented recovery procedures, combined with Multi-AZ, give the platform a stronger response to infrastructure failures and data incidents.
Running a mission-critical platform on AWS? We help it stay available, secure and recoverable as you grow.
How Cloudico moved a production SaaS container platform to Amazon EKS using Terraform, Helm, Argo CD, Karpenter, Prometheus and Grafana.

A growing SaaS company ran its production containers on Amazon ECS. It had been reliable, but the team now needed more flexibility, standard deployment workflows, better automation and access to the wider Kubernetes ecosystem.
The goal was not just to move containers. It was to build a production-ready Kubernetes platform for future growth, with less manual work, and to do it without any customer-facing downtime.
Argo CD continuously compares the state in Git with what runs in EKS, so nobody applies manifests by hand.
Two layers work together, so both the application and the compute underneath respond on their own.
When demand drops, Karpenter consolidates or removes unused nodes, so the cluster does not keep paying for idle capacity.
Production moved step by step, not in one switch. Readiness probes and rolling updates meant traffic only ever reached healthy pods.
Terraform provisions Amazon EKS, the VPC and networking, managed node groups, IAM roles and policies, Security Groups, the AWS Load Balancer Controller, Metrics Server and Karpenter. Infrastructure changes are now reviewed, versioned and applied the same way every time.
ECS task definitions and services were mapped to Kubernetes Deployments, Services, ConfigMaps, Secrets, resource requests and limits, health and readiness probes, autoscaling and ingress. Each workload was adapted to run properly on Kubernetes rather than copied line for line.
Applications were packaged as reusable Helm charts. Development, staging and production share the same templates, with environment-specific values files, which removed duplicated manifests and made releases predictable.
Prometheus collects cluster and workload metrics, Grafana provides dashboards, and CloudWatch covers AWS metrics, logs and alarms. Monitoring spans cluster, node and pod health, CPU and memory, latency, error rates, autoscaling and Karpenter activity.
IAM Roles for Service Accounts (IRSA) give each workload its own least-privilege AWS role instead of broad node permissions. Worker nodes are private, exposure is controlled through the Application Load Balancer, and TLS certificates come from AWS Certificate Manager.
Planning a move from ECS to EKS? Networking, IAM, autoscaling, GitOps and cutover all need to work together.
How Cloudico helped a US-based AI SaaS platform fix AWS security findings, strengthen cloud controls and move closer to SOC 2.

A fast-growing AI SaaS platform was preparing for SOC 2 and had to resolve security and infrastructure findings raised in Drata.
Turning checks green was not enough. The client was running live production on AWS, so every fix had to improve real security and auditability without causing downtime, breaking dependencies or slowing the engineering team.
A technically correct security change can still break production if IAM relationships, networking or workload dependencies are ignored. Every fix followed the same path.
Reviewed users, roles and policies, tightened account and password controls, reduced excessive and privileged permissions, and applied least privilege across service roles.
Configured AWS CloudTrail to trace authentication, IAM changes, resource and security configuration changes, and API activity, giving auditors stronger evidence.
Strengthened CloudWatch alarms with SNS notifications for key events, and enabled VPC Flow Logs so abnormal activity can be spotted and investigated.
Improved EBS encryption, hardened S3 with public-access restrictions and access reviews, and applied encryption at rest to protect application and business data.
Configured AWS Backup and EBS backup protection, reviewed retention and coverage for critical resources, and enabled DynamoDB Point-in-Time Recovery where required.
Reviewed EC2, Lambda, ALB, VPC, S3, EBS, DynamoDB and related services against AWS best practices, with care for existing architecture and uptime.
Amazon EC2AWS LambdaApplication Load BalancerAmazon VPCAmazon S3Amazon EBSAmazon DynamoDBAWS IAMAWS CloudTrailAmazon CloudWatchAmazon SNSAWS Backup
Seeing AWS findings in Drata, Vanta, Secureframe or another compliance platform? We fix the underlying configuration without slowing your team.
Pick the situation closest to yours and jump straight to the relevant engagement.